On This Page
Why Business Automations Fail: 10 Causes and How to Design for Recovery
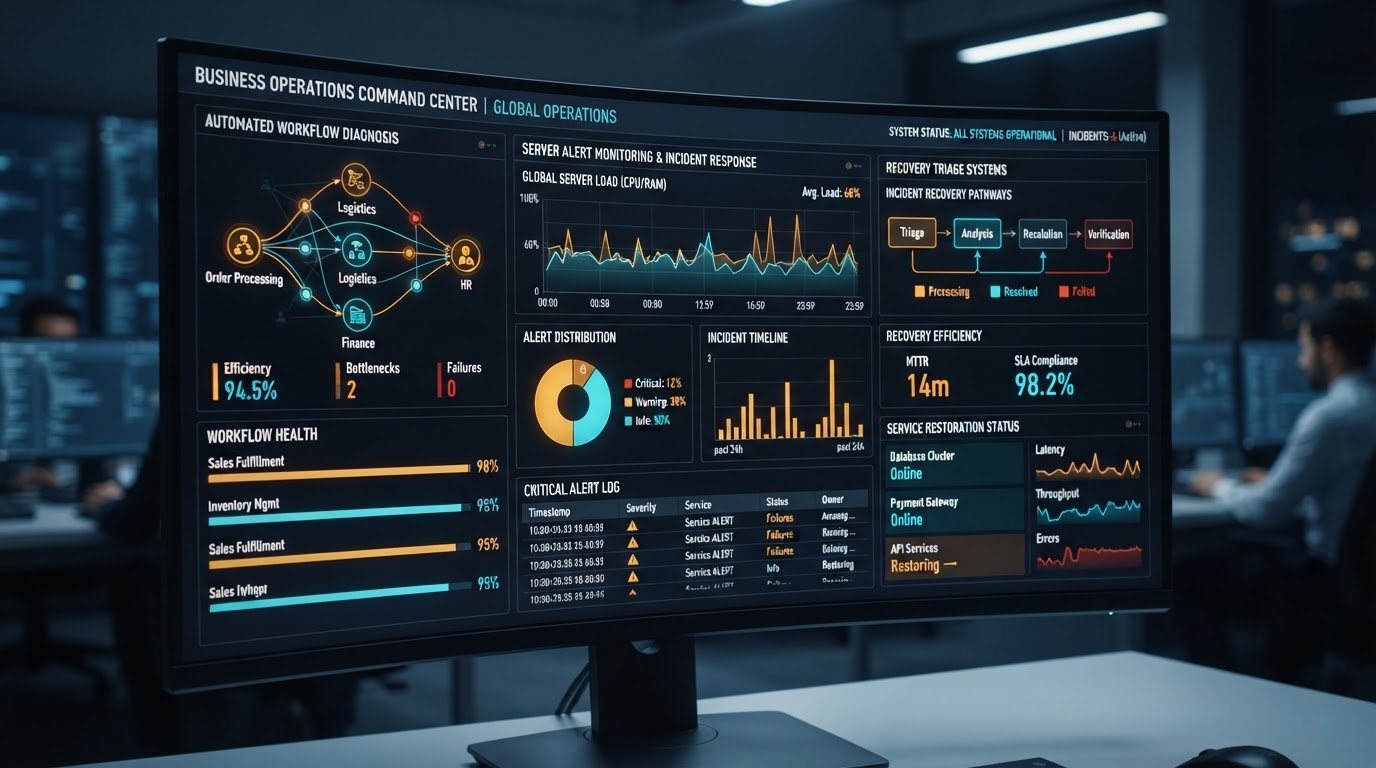
Every business that automates eventually experiences an automation failure. The question isn't whether your automations will break — it's whether the breakage will be a minor blip that your monitoring catches in minutes, or a silent revenue leak that goes unnoticed for weeks. After building, deploying, and maintaining hundreds of automations across dozens of businesses, the failure patterns are remarkably consistent: the same 10 causes account for 90% of automation failures, and the same design patterns prevent 90% of those failures from becoming business emergencies. This guide is an honest catalog of what breaks, why it breaks, and — most importantly — how to design automations that fail gracefully, recover automatically, and alert you before the failure becomes a crisis. If you're building automations or relying on them for revenue, this is the failure-mode guide you wish you'd read before the first one broke.
01Causes 1–3: The Integration Failures
Cause 1: API changes by a vendor. The most common failure: a vendor updates their API — renames a field, changes a response format, deprecates an endpoint — and your automation breaks because it expected the old format. This is not a hypothetical; it happens regularly as SaaS products iterate. The design pattern: defensive coding that validates API responses against an expected schema before processing, and alerts if the schema doesn't match. Don't trust that the API will always return the shape it returned last month — validate it every time.
Cause 2: Authentication expiry. The second most common: an OAuth token expires or a API key is rotated, and the automation fails silently because it can't authenticate. The failure is 'silent' because the workflow may not error visibly — it may just return empty data or skip the action. The design pattern: proactive token refresh (OAuth tokens should be refreshed before they expire, not after), alerting on authentication failures (don't let them pass silently), and a fallback authentication method for critical workflows. The automation monitoring best practices framework covers the alerting architecture that catches these.
Cause 3: Rate limiting. As your volume grows, you may hit a vendor's rate limit — the API returns 429 (Too Many Requests) and the automation fails. The design pattern: respect rate limit headers (most APIs return 'Retry-After' and 'X-RateLimit-Remaining' headers), implement exponential backoff for 429 responses, and monitor your usage against the limits. If you're consistently hitting limits, it's a sign to upgrade your plan or batch your requests. The Zapier vs Make comparison covers how each platform handles rate limiting differently — Make's error routing is generally more robust for high-volume workflows.
02Causes 4–6: The Data Failures
Cause 4: Data format drift. The data your automation receives changes format — a lead submits a phone number with a country code (+1 instead of just the number), a date in a new format, a name with special characters — and your parsing logic breaks. The design pattern: validate and normalize data at the entry point. Don't assume the format will always be the same; write parsing logic that handles common variations (with/without country code, with/without dashes, different date formats) and rejects data that can't be parsed rather than passing garbage downstream.
Cause 5: Missing or null data. The automation expects a field that isn't present — the form was changed and a field was removed, or the lead didn't fill it in — and the workflow breaks because it tries to process a null value. The design pattern: defensive access that handles nulls gracefully (default values, conditional logic that skips missing fields) and validation that checks for required fields before processing. A workflow that crashes on a null field is fragile; one that defaults to a sensible value and logs the missing field is robust. The CRM migration checklist guide covers the data validation patterns that prevent these failures during and after migrations.
Cause 6: Duplicate or contradictory data. Two workflows update the same record simultaneously, or a duplicate lead is created, and the automation processes the wrong version or creates a conflict. The design pattern: idempotency keys (each execution carries a unique key, and the system checks if it's been processed), record locking (prevent simultaneous updates to the same record), and deduplication logic (match on phone/email before creating a new record). This is the architecture pattern that prevents the 'duplicate invoice' and 'two confirmation emails' failures that erode customer trust.
03Causes 7–8: The Logic and Design Failures
Cause 7: Edge cases not handled. The automation works for 95% of inputs but fails on the 5% that weren't considered: a lead with no last name, an appointment outside business hours, a service type that doesn't exist in the routing logic. The design pattern: explicit edge-case handling (list the edge cases and handle each), a fallback route (any input that doesn't match the expected patterns goes to a human for review rather than failing), and testing with edge-case inputs before deployment. The automated lead qualification framework covers the 'gray zone' pattern — edge cases that the automation can't confidently handle go to a human rather than being force-classified.
Cause 8: Over-automation. The automation tries to handle too much — it tries to complete the entire workflow autonomously, including the parts that need human judgment — and the result is worse than the manual process it replaced. The design pattern: clear boundaries on what the automation does and doesn't do. The automation handles the routine (capture, route, notify); the human handles the judgment (qualify, negotiate, close). Over-automation is the failure mode where the technology is technically working but the outcome is worse than the manual process — and it's the failure mode that's hardest to detect because the automation 'succeeds' while producing a bad result. The AI agent vs chatbot framework clarifies the boundaries — each layer does what it's best at, and the human handoff is a designed step, not a failure.
04Causes 9–10: The Infrastructure and Human Failures
Cause 9: Third-party outages. The email provider goes down, the SMS gateway has an outage, the CRM is unavailable — and the automation fails because a dependency is down. The design pattern: retry with backoff (retry after 1 minute, then 5, then 30, then alert), fallback channels (if email fails, send via SMS; if both fail, queue for retry), and circuit breakers (if a dependency fails repeatedly, stop trying and alert rather than hammering a down service). The lead response time automation framework covers the multi-channel fallback pattern — if the primary channel is down, the secondary takes over.
Cause 10: Team dependency and knowledge loss. The person who built the automation leaves, and no one else understands how it works or how to fix it. The automation breaks, and the institutional knowledge to repair it walked out the door. The design pattern: documentation (every automation should have a documented architecture, trigger, action, and owner), cross-training (at least two people should understand each critical automation), and managed maintenance (an external team that maintains the automation so it's not dependent on a single employee). The in-house AI hiring vs on-demand analysis covers this risk in detail — the single-point-of-failure is one of the strongest arguments for a managed model over a single in-house hire.
05Designing for Recovery: The Graceful Failure Pattern
The goal isn't to prevent all failures — that's impossible. The goal is to fail gracefully: when the automation breaks, the failure is visible, recoverable, and non-destructive. The graceful failure pattern has five components: (1) visibility — the failure is logged and alerted, not silent; (2) containment — the failure affects only the specific record or execution, not the entire system; (3) recovery — the automation retries transient failures automatically and escalates permanent ones to a human; (4) idempotency — a retried execution doesn't create duplicates; (5) fallback — if the primary path fails, a secondary path takes over.
The most important design principle is to make failures visible. A silent failure — the automation 'succeeds' but produces wrong output — is the most dangerous failure mode because it goes unnoticed and the wrong output compounds. A visible failure — the automation errors, alerts you, and produces no output — is safer because you know something's wrong and can fix it. Prefer a loud failure over a quiet wrong answer. The automation monitoring best practices framework covers the monitoring architecture that makes failures visible; the design principle here is to build the automation to fail loudly, not quietly.
The human handoff is the ultimate recovery mechanism. When the automation can't handle a case — whether it's an edge case, a data format it doesn't recognize, or a third-party outage — the default behavior should be to route to a human, not to fail silently. The human receives the context, resolves the case manually, and the outcome feeds back into the automation as a training data point. This is the 'closed loop' pattern that separates a resilient automation system from a fragile one: the automation handles 90%, the human handles the 10%, and every human intervention makes the automation smarter for the next time. The chatbot human handoff guide covers this pattern for chatbots — the same principles apply to any automation that needs a graceful failure mode.
06Building a Resilient Automation Stack
The resilient automation stack is built on four layers. Layer 1: Validation — every input is validated before processing; every API response is checked against an expected schema; missing or malformed data is caught at the entry point, not three steps downstream. Layer 2: Retry and recovery — transient failures (5xx, 429, timeouts) are retried with exponential backoff; permanent failures (4xx, authentication errors) are alerted immediately; idempotency keys prevent duplicates on retry.
Layer 3: Monitoring and alerting — health checks verify that each workflow is running; performance monitoring tracks execution time and error rates; alerts fire on patterns (error rate > 5% for 3 runs, execution time > 2x baseline) rather than individual errors. Layer 4: Human escalation — when the automation can't handle a case, it routes to a human with full context, and the human's resolution feeds back into the system. This four-layer architecture is what we deploy for every client — and it's the difference between an automation that runs for months without intervention and one that breaks weekly.
The investment in resilience pays for itself the first time a failure would have been a crisis. A monitoring layer that catches an API change in 5 minutes (instead of 5 days) saves the revenue that would have leaked during the silent failure. A retry layer that handles a 30-minute third-party outage without dropping a single lead saves the customers that would have been lost. A human escalation layer that catches the edge case before it becomes a customer complaint saves the reputation that takes years to build. The automation ROI calculator framework helps quantify the cost of downtime — because resilience isn't an expense; it's insurance for the revenue your automations generate. And the business processes to automate before hiring framework helps you prioritize which processes are worth the investment in resilience — because not every automation needs the full four-layer treatment, but the mission-critical ones absolutely do.
Key Takeaways
- The 10 most common causes of automation failure are API changes, auth expiry, rate limiting, data format drift, missing data, duplicates, edge cases, over-automation, third-party outages, and knowledge loss — all preventable with the right design.
- Design for graceful failure: make failures visible (not silent), contained (not system-wide), recoverable (retry transient, escalate permanent), idempotent (no duplicates), and fallback-ready (secondary paths).
- A silent failure that produces wrong output is more dangerous than a loud failure that produces no output — prefer a visible error over a quiet wrong answer.
- The human handoff is the ultimate recovery mechanism — route cases the automation can't handle to a human with full context, and feed the resolution back to improve the system.
- Build a four-layer resilient stack: validation, retry/recovery, monitoring/alerting, and human escalation — the investment pays for itself the first time it prevents a crisis.
Written by Moise
Founder & Lead Automation ArchitectMoise is the founder and lead automation architect at Wootomatic. With over a decade of hands-on experience designing, implementing, and maintaining high-throughput business automations, CRM pipelines, and custom AI agents, he has architected mission-critical workflows for hundreds of appointment-based and field-service businesses. His focus is on resilient, monitored systems that produce measurable ROI without fragile software bloat.
Ready to Put This Into Action?
Tell us about your workflow and we'll scope a custom automation within 24 hours.
Start Your Automation Project